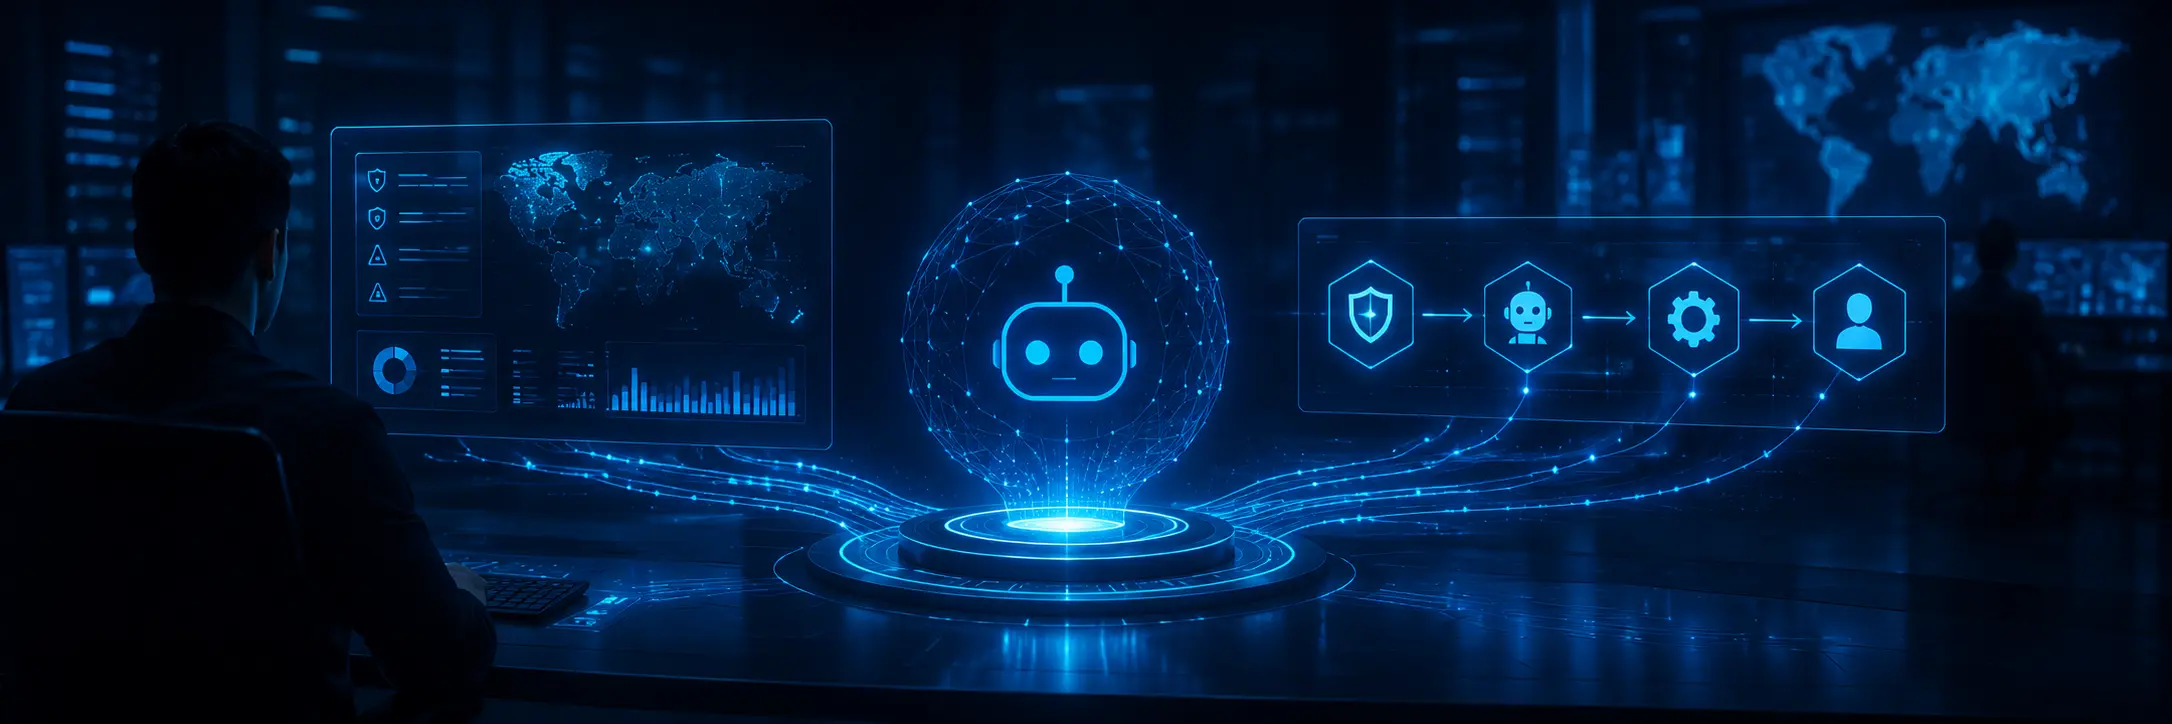
An Agentic SOC is a security operations centre in which AI agents independently triage, enrich, investigate and act on alerts within defined policy guardrails, escalating to human analysts only when judgement or authority is required. Unlike fixed automation scripts, these agents reason over context, choose their next step, and follow an investigation wherever the evidence leads. The result is a security operations model where the bulk of routine detection and response work is carried out by software that behaves less like a rule and more like a junior analyst. This article explains how the agentic SOC works, how it differs from traditional automation, and why it has become the dominant architectural direction for modern security operations.

What is an agentic SOC?

The term agentic refers to AI systems that can pursue a goal across multiple steps, making decisions at each stage rather than executing a single pre-programmed instruction. In a security context, an agentic SOC applies this capability to the alert lifecycle. When a detection fires, an AI agent does not simply forward it to a queue. It interprets the alert, gathers the surrounding evidence, forms a hypothesis about whether the activity is malicious, tests that hypothesis against further data, and then either resolves the alert, contains the threat, or hands a structured case to a human.

This matters because the volume of alerts in a typical environment far exceeds what human teams can examine. Most alerts are benign or low priority, yet each still demands attention. Agentic AI in cybersecurity addresses this by giving every alert a genuine investigation, not just a rule match, at a scale and speed that human staffing cannot reach.

How does an agentic SOC differ from SOAR and traditional automation?

Security teams have automated parts of their work for years through SOAR platforms and scripted playbooks. The difference between that approach and an agentic SOC is the difference between a fixed recipe and a decision-maker. A SOAR playbook executes a predetermined sequence: if condition A, perform action B. It cannot deviate, reason about an unusual case, or decide that the evidence points somewhere the author never anticipated. When reality does not match the playbook, the case stalls or escalates by default.

An agentic system, by contrast, selects its own actions based on what it finds. It can pivot from an endpoint alert to identity data to network telemetry because the investigation warranted it, not because a branch was hard-coded for that path. This makes autonomous alert triage adaptive rather than brittle.

Dimension Traditional automation / SOAR Agentic SOC
Decision model Pre-defined if/then playbooks Goal-driven reasoning at each step
Handling novel cases Escalates or stalls when no rule matches Investigates dynamically using available evidence
Investigation depth Fixed enrichment steps Pursues evidence across data sources as needed
Maintenance Playbooks require constant manual tuning Adapts to context with policy-level oversight
Output Enriched ticket for human review Resolved alert or structured case with reasoning

Key takeaways

  • An agentic SOC uses AI agents that triage, enrich, investigate and act on alerts within policy guardrails, escalating to humans by exception.
  • It differs from SOAR and scripted automation by reasoning over context and choosing its own next step rather than following fixed playbooks.
  • The agent workflow follows clear stages: detect, triage, enrich, investigate, decide, act and document.
  • Guardrails and human oversight keep high-impact actions reversible, scoped and approvable, with a full decision trail.
  • EU AI Act transparency obligations applying from August 2026 reinforce the need for explainable automated decisions, which agentic systems are built to provide.

The agentic SOC workflow: how AI agents run security operations

The work of an agentic SOC can be understood as a repeatable sequence of stages. Each stage is something a human analyst would otherwise perform manually, now carried out by an AI SOC analyst that documents its reasoning as it goes.

  • Detect: a signal arrives from an endpoint, identity provider, network sensor or log source.
  • Triage: the agent assesses severity, deduplicates against related signals and decides whether the alert merits deeper work.
  • Enrich: it gathers context such as asset criticality, user behaviour, threat intelligence and historical activity.
  • Investigate: it forms and tests hypotheses, pivoting across data sources and mapping observed behaviour to known adversary techniques.
  • Decide: it reaches a conclusion: benign, suspicious or malicious, with a confidence assessment.
  • Act: within its guardrails, it resolves the alert, takes a contained response action, or escalates a structured case to a human.
  • Document: it records the full chain of reasoning and evidence so the decision can be reviewed and audited.

This is the practical meaning of AI agents in cybersecurity: not a single model answering a question, but a coordinated workflow that mirrors how a skilled analyst actually thinks and works.

Guardrails and human oversight in an agentic SOC

Autonomy without constraint is unacceptable in security operations, where a wrong action can disrupt a business as severely as the threat it was meant to stop. An agentic SOC is therefore defined as much by its guardrails as by its capabilities. Guardrails specify what an agent may do on its own, what requires approval, and what is never permitted without a human decision.

In practice this means high-impact actions, such as isolating a critical server or disabling a privileged account, are scoped, reversible where possible, and subject to policy. Lower-impact actions, such as closing a confirmed false positive or isolating a single non-critical endpoint, can proceed automatically because the blast radius is small and the action is recoverable. Human oversight is preserved through clear escalation paths, approval gates for sensitive operations, and a complete record of every decision the agent made and why. This is the foundation of safe autonomous containment: the goal is fast action that remains accountable and within defined limits.

Agentic AI security and the EU AI Act transparency obligations

Explainability is not only good practice; it is becoming a regulatory expectation. The EU AI Act introduces transparency obligations that apply from August 2026, requiring that certain automated decisions be explainable and that organisations can account for how those decisions were reached. For security leaders, this places a clear demand on any system that takes automated action: it must be able to show its reasoning.

Agentic AI security aligns naturally with this requirement. Because each agent documents its investigation, evidence and decision rationale at every stage, the audit trail is a built-in property of the architecture rather than an afterthought. This complements existing obligations under DORA, in force since 17 January 2025, and the operational expectations introduced by NIS2, adopted in 2022. An agentic SOC that records its reasoning makes regulatory demonstration of control far more tractable than opaque automation ever could.

Why the agentic SOC is the current architectural direction

The shift towards agentic operations is driven by a structural mismatch: alert volumes and attacker speed continue to rise, while skilled analysts remain scarce and expensive. Scripted automation reduced some of the load but could not investigate, and adding more analysts does not scale economically or sustainably. An architecture in which AI agents perform the investigative work, supervised by humans who concentrate on judgement, complex cases and strategy, resolves that mismatch directly. It is a continuation of the broader move described in what an AI SOC is, taken to the point where the AI is an active operator rather than an assistant.

Vokter applies this model in practice. In its Autonomous mode, AI agents run the full triage and response workflow without requiring a SIEM or an in-house team, operating directly from endpoint or event-collector telemetry. In Guardian mode, the same agentic engine handles the large majority of detection and response work, while named Nordic analysts take on critical cases, threat hunting and forensics under a defined service level agreement. The agentic SOC is not a single product feature; it is the operating model, with the degree of human involvement chosen to match each organisation’s risk appetite and resources. Organisations evaluating the model can discuss their requirements against these modes.

Conclusion

The agentic SOC marks a genuine change in how security operations are run. By giving AI agents the ability to reason, investigate and act within firm guardrails, it brings real investigation to every alert at a scale humans cannot match, while keeping people in control of consequential decisions. As transparency and resilience obligations tighten across the EU, the explainable, documented nature of agentic operations becomes not just an efficiency gain but a compliance advantage. It is, for these reasons, the direction in which modern security operations are now moving.
You have endpoint detection, a SIEM, identity monitoring, email security and 24/7 coverage. You made the investments and checked the boxes and investigations still take too long, analysts are still buried, and the tools still do not quite talk to each other. The instinct is to question the stack. Usually the stack is fine. The failure is in the operational layer that is supposed to tie it together the Level 1 work and that layer is exactly what an AI-native SOC automates.

Key takeaways

  • A decade of security budget went to detection tools and almost none to the operations that connect detection to response.
  • Each tool sees only part of an attack; the truth is in the correlation across them, and a human is usually the slow, lossy integration layer.
  • Neither the SIEM (a data problem) nor SOAR (known playbooks) closes the gap; both still assume a human investigates.
  • An operational layer that automates L1 correlation, investigation, first-line response closes it without replacing your stack.

The real failure point is not detection

Detection is rarely where modern security operations fail. Your tools surface plenty; the industry’s problem was never a shortage of alerts. The breach happens in the gap between detection and response the window where an alert sits in a queue, gets a partial look, loses context at a hand-off, and waits for someone to connect it to the two related signals sitting in other consoles. That gap is measured in dwell time, and dwell time is an operations metric, not a detection one. No additional detection product shortens it.

The seam problem, with a real example

Every tool has a partial view, and attackers move across the seams between them. Consider a realistic account-takeover sequence:

  • Your identity provider flags an unusual sign-in new country, but the session passes MFA. On its own: low severity, plausibly a travelling employee.
  • Minutes later, your email security notes a new inbox rule auto-forwarding finance mail to an external address. On its own: medium, and rules get created all the time.
  • Your cloud logs record an OAuth token grant to a third-party app. On its own: low, users grant app access constantly.

Three tools, three unremarkable alerts, each easily auto-closed in isolation. Correlated, they are a textbook account takeover in progress. The signal was never in any single tool it was in the relationship between them, in a tight time window, tied to one identity. A human can absolutely see this, if a human happens to look at all three consoles in the same ten minutes and remembers the first alert while reading the third. Under real queue pressure, that is exactly what does not happen.

Why the SIEM didn’t fix this

The SIEM was supposed to solve exactly this by centralising the data and it solved the data problem. But centralising logs is not the same as operationalising them. Someone still has to author and tune the correlation rules, keep them current as the environment changes, and then investigate what they surface. In practice the SIEM often becomes an expensive, noisy data lake that raises more alerts than anyone trusts. The data is in one place; the operations are still manual.

Why SOAR didn’t fix it either

SOAR promised automation, and it delivers for the cases you can write down in advance. A playbook is superb at executing a known response: this alert, these steps, in this order. But a playbook cannot investigate a situation nobody pre-scripted, and it breaks when reality diverges from the runbook. SOAR automates the response to the known; it does not automate the investigation of the unknown, which is the part that actually consumes L1.

The missing operational layer

What has been missing is a layer above the stack that does the connective, investigative work automatically the work SOCs staff with L1 analysts. An AI-native SOC continuously correlates telemetry across identity, endpoint, cloud, email and network; maintains investigative context across an incident instead of losing it at every hand-off; enriches and scores each case; resolves or safely contains the clear ones; and surfaces only what needs a human with the investigation already assembled. In the takeover example above, that layer sees all three signals against one identity in one window and raises a single, high-confidence case while the attack is still early. It is also what ends alert fatigue, because analysts stop wading through the noise the layer has already resolved.

Escalation-based MDR vs an operational layer

Dimension Traditional / escalation MDR AI-native operational layer
What you receive Alerts to investigate Verdicts and outcomes
Cross-tool correlation Left to your team Automatic, every case
Investigative context Rebuilt per hand-off Maintained across the incident
Unknown scenarios Human-dependent Investigated on their merits
Your existing stack Often duplicated or replaced Kept and coordinated
Primary output Reduced detection gaps Reduced detection-to-response gap

What fixing it looks like your stack stays

Closing this gap does not mean ripping anything out. Sentinel, Splunk, CrowdStrike, Defender, Okta they stay exactly where they are. What changes is the layer above them: alerts start arriving with cross-tool context already attached, investigations stop fragmenting across six consoles, and response timelines compress not because you hired more analysts, but because the connective work that was slowing everything down now runs automatically and continuously. This is the outcome that separates real managed detection and response from monitoring that simply escalates, and it is how you get genuine 24/7 coverage without a night-shift rota.

“But we already have MDR / SOAR”

Two fair objections. First: we have an MDR. Most MDR is escalation-based it detects and hands you alerts, leaving the correlation and response to you; the seam problem survives it. Ask whether yours delivers alerts or outcomes. Second: we have SOAR. SOAR is valuable for automating known response steps, but it executes playbooks; it does not investigate the unscripted, and the account-takeover sequence above is precisely the kind of emergent case no playbook was written for. An operational layer complements both it is the investigative first line that turns your detections and your playbooks into decisive action.

Close the gap with Vokter

Vokter is that operational layer. It sits on top of the stack you already run and automates the Level 1 first line cross-tool correlation, investigation to a verdict, and safe first-line response so detection finally turns into action. Add it over your existing SIEM/XDR with Vokter Hybrid, run it as your whole first line with Vokter Autonomous, or add named Nordic analysts and an SLA with Vokter Guardian operated within EU jurisdiction throughout. Find out what is slipping through the seams.

To achieve 24/7 SOC coverage without running a night shift, route first-line detection and triage to an AI SOC that operates continuously, then escalate only confirmed, prioritised incidents to your people during working hours or to a managed analyst team under an SLA. The AI handles the relentless overnight volume; humans handle judgement. This gives a lean security team genuine round-the-clock protection without recruiting, training and retaining staff across multiple shifts.

Attackers do not keep office hours. Ransomware deployment, credential abuse and lateral movement are frequently timed for evenings, weekends and public holidays precisely because that is when defenders are thin. The practical question for most mid-market organisations is not whether they need after-hours security monitoring, but how to fund and sustain it.

Key takeaways

  • True 24/7 SOC coverage requires multiple shifts, holiday and sickness cover, and continuous training, which is difficult for a lean security team to staff in-house.
  • The realistic options are building in-house, follow-the-sun arrangements, outsourcing to MDR or SOC-as-a-service, and AI-led continuous monitoring, each with distinct trade-offs.
  • An AI SOC provides continuous first-line detection and triage, so a small team is no longer the bottleneck for round-the-clock coverage.
  • Vokter Autonomous delivers continuous coverage with no in-house team; Vokter Guardian adds named Nordic analysts on a 24/7 SLA.
  • The strongest models combine automation for first response with human escalation for judgement, containment decisions and forensics.

Why 24/7 SOC coverage is so hard to staff

Continuous monitoring sounds like a scheduling problem. It is closer to a workforce problem. Covering every hour of every day means operating several rotating shifts, then layering cover on top for annual leave, sickness, training and inevitable attrition. Night and weekend rotations are unpopular, burn analysts out faster, and intensify the well-documented shortage of experienced security staff.

The hidden cost is quality. Overnight shifts often see the least experienced analysts facing the highest-stakes alerts with the least support. Alert fatigue compounds the problem: when a tired analyst is wading through thousands of low-value notifications, genuine threats are easy to miss. This is why so many lean teams technically have after-hours security monitoring on paper, yet still discover breaches days later.

The options for round-the-clock SOC coverage

There are four broad routes to continuous coverage. Most organisations end up combining them rather than choosing one outright.

Option How it works Best suited to Key trade-off
Build in-house Recruit enough analysts to staff continuous shifts internally Large enterprises with deep budgets and existing SOC maturity Highest cost; hardest to staff and retain across night and weekend rotations
Follow-the-sun Hand off monitoring between teams in different time zones Multinational organisations with offices across regions Requires distributed teams and tight handover discipline; rarely viable for a single-country mid-market firm
Outsource to MDR / SOC-as-a-service A provider supplies analysts, tooling and processes as a service Teams that want human coverage without building it themselves Coverage and data residency vary by provider; you depend on their staffing and response quality
AI SOC Automation performs continuous detection, triage and investigation, escalating to humans Lean teams needing genuine 24/7 coverage without a night shift Requires confidence in autonomous handling; works best with a human escalation path

Building in-house and follow-the-sun both assume scale that most Nordic and DACH mid-market organisations simply do not have. That leaves outsourcing and automation as the realistic levers, and increasingly the two are combined. For a fuller comparison of the managed route, see our guide to SOC-as-a-service in the Nordics and an overview of what MDR is.

How an AI SOC delivers 24/7 SOC coverage without a night shift

An AI SOC changes the economics of continuous coverage because the system that watches your environment overnight is not a person on a rota. It ingests telemetry, correlates signals, investigates suspicious activity and triages alerts continuously, at a volume and consistency no shift pattern can match. Crucially, it does not get tired at 03:00, and it applies the same investigative rigour at every hour.

This directly attacks the SOC staffing problem. Instead of needing analysts present around the clock, you need them available to act on the small number of confirmed, contextualised incidents the AI escalates. The overnight noise that drives alert fatigue is resolved before anyone is woken. To understand how this works in practice, see how AI handles alert triage and alert fatigue.

Good automation is transparent about what it did and why. Each escalation should arrive with the evidence, the investigative steps taken and a recommended action, so the receiving human can make a fast, informed decision rather than starting an investigation from scratch.

Where humans still matter

Automation is not a replacement for judgement. Decisions about disruptive containment, communication with leadership, regulatory notification and deep forensic analysis benefit from human expertise. The honest position is that an AI SOC is exceptional at first-line coverage and triage, and humans remain essential for the complex, high-consequence end of incident response. A well-designed service makes the handoff between the two seamless.

Choosing between no team and a hybrid analyst model

Two configurations suit lean teams needing round-the-clock SOC coverage, and the right one depends on whether you want any in-house involvement at all.

Vokter Autonomous provides continuous, SIEM-less detection and response with no in-house SOC team required. It is built for organisations that have neither the staff nor the appetite to run security operations themselves, but still need genuine 24/7 protection. The AI performs first-line monitoring around the clock and surfaces only what matters.

Vokter Guardian pairs that same continuous AI coverage with named Nordic analysts available 24/7 under a contractual SLA. The AI handles the large majority of detection and triage; experienced analysts provide threat hunting, forensics and escalation support, with defined response commitments. This is the model for teams that want automation to carry the overnight load while retaining human accountability and a guaranteed response.

If you are weighing providers, our guidance on choosing an AI SOC provider in Europe sets out the questions worth asking. When you are ready to discuss coverage for your environment, get in touch.

What to look for in after-hours security monitoring

  • Genuine continuity, not on-call. Confirm that monitoring is truly continuous, not a pager that wakes someone who then logs in.
  • Clear escalation paths. Know exactly what is handled autonomously, what is escalated, and how quickly.
  • Contextualised alerts. Every escalation should carry the evidence and reasoning, not just a notification.
  • Defined response commitments. An SLA turns “we monitor 24/7” into a measurable obligation.
  • EU data sovereignty. For Nordic and EU organisations, telemetry should remain within EU cloud regions under EU jurisdiction, which also supports obligations under NIS2 and DORA.

Conclusion

Round-the-clock protection no longer depends on filling a night-shift rota. By routing continuous first-line detection and triage to an AI SOC and reserving human expertise for genuine incidents, a lean security team can achieve 24/7 SOC coverage that is consistent, sovereign and sustainable. Whether you choose continuous coverage with no in-house team or an AI-plus-analyst model under an SLA, the night shift is no longer the price of staying protected after dark.

You have endpoint detection, a SIEM, identity monitoring, email security and 24/7 coverage. You made the investments and checked the boxes — and investigations still take too long, analysts are still buried, and the tools still do not quite talk to each other. The instinct is to question the stack. Usually the stack is fine. The failure is in the operational layer that is supposed to tie it together — the Level 1 work — and that layer is exactly what an AI-native SOC automates.

Key takeaways

  • A decade of security budget went to detection tools and almost none to the operations that connect detection to response.
  • Each tool sees only part of an attack; the truth is in the correlation across them, and a human is usually the slow, lossy integration layer.
  • Neither the SIEM (a data problem) nor SOAR (known playbooks) closes the gap; both still assume a human investigates.
  • An operational layer that automates L1 — correlation, investigation, first-line response — closes it without replacing your stack.

The real failure point is not detection

Detection is rarely where modern security operations fail. Your tools surface plenty; the industry’s problem was never a shortage of alerts. The breach happens in the gap between detection and response — the window where an alert sits in a queue, gets a partial look, loses context at a hand-off, and waits for someone to connect it to the two related signals sitting in other consoles. That gap is measured in dwell time, and dwell time is an operations metric, not a detection one. No additional detection product shortens it.

The seam problem, with a real example

Every tool has a partial view, and attackers move across the seams between them. Consider a realistic account-takeover sequence:

  • Your identity provider flags an unusual sign-in — new country, but the session passes MFA. On its own: low severity, plausibly a travelling employee.
  • Minutes later, your email security notes a new inbox rule auto-forwarding finance mail to an external address. On its own: medium, and rules get created all the time.
  • Your cloud logs record an OAuth token grant to a third-party app. On its own: low, users grant app access constantly.

Three tools, three unremarkable alerts, each easily auto-closed in isolation. Correlated, they are a textbook account takeover in progress. The signal was never in any single tool — it was in the relationship between them, in a tight time window, tied to one identity. A human can absolutely see this, if a human happens to look at all three consoles in the same ten minutes and remembers the first alert while reading the third. Under real queue pressure, that is exactly what does not happen.

Why the SIEM didn’t fix this

The SIEM was supposed to solve exactly this by centralising the data — and it solved the data problem. But centralising logs is not the same as operationalising them. Someone still has to author and tune the correlation rules, keep them current as the environment changes, and then investigate what they surface. In practice the SIEM often becomes an expensive, noisy data lake that raises more alerts than anyone trusts. The data is in one place; the operations are still manual.

Why SOAR didn’t fix it either

SOAR promised automation, and it delivers — for the cases you can write down in advance. A playbook is superb at executing a known response: this alert, these steps, in this order. But a playbook cannot investigate a situation nobody pre-scripted, and it breaks when reality diverges from the runbook. SOAR automates the response to the known; it does not automate the investigation of the unknown, which is the part that actually consumes L1.

The missing operational layer

What has been missing is a layer above the stack that does the connective, investigative work automatically — the work SOCs staff with L1 analysts. An AI-native SOC continuously correlates telemetry across identity, endpoint, cloud, email and network; maintains investigative context across an incident instead of losing it at every hand-off; enriches and scores each case; resolves or safely contains the clear ones; and surfaces only what needs a human — with the investigation already assembled. In the takeover example above, that layer sees all three signals against one identity in one window and raises a single, high-confidence case while the attack is still early. It is also what ends alert fatigue, because analysts stop wading through the noise the layer has already resolved.

Escalation-based MDR vs an operational layer

Dimension Traditional / escalation MDR AI-native operational layer
What you receive Alerts to investigate Verdicts and outcomes
Cross-tool correlation Left to your team Automatic, every case
Investigative context Rebuilt per hand-off Maintained across the incident
Unknown scenarios Human-dependent Investigated on their merits
Your existing stack Often duplicated or replaced Kept and coordinated
Primary output Reduced detection gaps Reduced detection-to-response gap

What fixing it looks like — your stack stays

Closing this gap does not mean ripping anything out. Sentinel, Splunk, CrowdStrike, Defender, Okta — they stay exactly where they are. What changes is the layer above them: alerts start arriving with cross-tool context already attached, investigations stop fragmenting across six consoles, and response timelines compress — not because you hired more analysts, but because the connective work that was slowing everything down now runs automatically and continuously. This is the outcome that separates real managed detection and response from monitoring that simply escalates, and it is how you get genuine 24/7 coverage without a night-shift rota.

“But we already have MDR / SOAR”

Two fair objections. First: we have an MDR. Most MDR is escalation-based — it detects and hands you alerts, leaving the correlation and response to you; the seam problem survives it. Ask whether yours delivers alerts or outcomes. Second: we have SOAR. SOAR is valuable for automating known response steps, but it executes playbooks; it does not investigate the unscripted, and the account-takeover sequence above is precisely the kind of emergent case no playbook was written for. An operational layer complements both — it is the investigative first line that turns your detections and your playbooks into decisive action.

Close the gap with Vokter

Vokter is that operational layer. It sits on top of the stack you already run and automates the Level 1 first line — cross-tool correlation, investigation to a verdict, and safe first-line response — so detection finally turns into action. Add it over your existing SIEM/XDR with Vokter Hybrid, run it as your whole first line with Vokter Autonomous, or add named Nordic analysts and an SLA with Vokter Guardian — operated within EU jurisdiction throughout. Find out what is slipping through the seams.

Frequently asked questions

How can a small team get 24/7 SOC coverage without a night shift?
Route continuous first-line detection and triage to an AI SOC that operates around the clock, then escalate only confirmed, prioritised incidents to your people during working hours or to a managed analyst team under an SLA. The automation absorbs the overnight volume, so you do not need analysts on rotating night shifts.
Why is staffing a 24/7 SOC in-house so difficult?
Continuous coverage requires several rotating shifts plus additional cover for annual leave, sickness, training and attrition. Night and weekend rotations are unpopular and accelerate burnout, and the shortage of experienced security analysts makes sustaining quality coverage at every hour especially hard for a lean security team.
What are the options for round-the-clock SOC coverage?
The main routes are building an in-house team, follow-the-sun handovers between time zones, outsourcing to MDR or SOC-as-a-service, and using an AI SOC for continuous monitoring. In-house and follow-the-sun assume scale most mid-market firms lack, so outsourcing and AI-led automation, often combined, are the realistic options.
Can an AI SOC handle overnight coverage on its own?
For first-line work, yes: it detects, investigates and triages continuously, resolving overnight noise before anyone is woken. But disruptive containment decisions, regulatory notification, leadership communication and deep forensics still need human expertise, so the strongest models pair continuous automation with a defined human escalation path.
What is the difference between Vokter Autonomous and Vokter Guardian for after-hours coverage?
Vokter Autonomous provides continuous, SIEM-less coverage with no in-house SOC team required. Vokter Guardian pairs the same continuous AI coverage with named Nordic analysts available 24/7 under a contractual SLA, adding threat hunting, forensics and defined response commitments for teams that want guaranteed human accountability.

Let’s Talk

    I have read, and consented to the Privacy Policy and Terms of Use.*